 dgtlmoonandClaude Opus 5
8d938b5966
* Browser fetchers - Judge a fetch on the document we end up extracting, not the first navigation

The goal is to compare the text of the page the browser lands on, even when the site navigates
again after the first response. Both fetchers were bound to the first navigation, which shows up
as two different bugs:

1. pyppeteer hangs until the hard processing timeout. Its navigation watcher is bound to the
   loaderId of the navigation it started, so when the site replaces that document the 'load' it
   waits for never arrives for that loaderId. With timeout=0 and setDefaultNavigationTimeout(0)
   there is nothing to break the wait, so goto() blocks until
   PUPPETEER_MAX_PROCESSING_TIMEOUT_SECONDS (180s) kills the fetch and the watch records an empty
   xpath_data - while the browser is sitting on a fully loaded page. Traced on slated.com:

     0.24s goto start
     0.74s main frame networkIdle    loaderId=A0E0E0B2   <- never gets 'load'
     2.72s main frame init           loaderId=56D2B5EF   <- re-navigated to get.slated.com
     3.49s main frame load           loaderId=56D2B5EF   <- fires for the new document
    25.2s  goto still hanging, frame._loaderId is now 56D2B5EF

   Now the navigation races goto() against the main frame firing 'load', bounded by
   BROWSER_NAVIGATION_TIMEOUT_SECONDS (default 30), and falls back to the document we can see.
   slated.com / getastra.com / addupsolutions.com went from a 180s timeout with no content to
   200 with full content in 5-35s.

2. Both fetchers reported the status of the interstitial. A site that gates unseen visitors with
   an error status plus a client-side redirect (reported against fotokoch.de: 503 + meta refresh,
   then a 200 with the real page) failed the watch even though the content was present, and the
   only workaround was ignore_status_codes, which also hides genuine 404s and 500s forever.
   The fetchers now keep the latest main-frame document response and judge on that - the refresh
   lands during the existing extra_wait, so the 200 wins.

Playwright also waits for a settled load state before extracting, which is what produced
"Execution context was destroyed, most likely because of a navigation" when the refresh collided
with extraction.

The navigation-response tracker is installed once per page and shared between the fetcher and
action_goto_url() rather than each navigation adding its own listener - 'response' fires once per
HTTP response, hundreds of times on a heavy page, so the callbacks are worth not duplicating.
Verified one listener remains after an install plus four navigations.

Selenium is unaffected either way - it hardcodes status_code = 200 because WebDriver cannot see
the HTTP status.

Tested: new test_renavigation.py covers the interstitial case end to end and was checked to fail
without the fix and pass with it, on both fetchers. The test endpoint gates on last-seen time
rather than a hit count, because a counter lets the second check see a clean 200 and the test
then passes without the fix. Full browser suite 11 passed on playwright and on pyppeteer, 494
unit tests pass.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>

* Puppeteer fetcher - One content-ready deadline instead of a stopLoading watchdog per frame event

Page.stopLoading is what stops a page that would otherwise load forever waiting on a subresource
that never answers, so that we can still screenshot and scrape what rendered. That intent was
right, but it was implemented as a fire-and-forget task armed by every frame event, which measured
on a single fetch of an iframe-heavy page came to:

  14 watchdog tasks spawned
  11 page-wide Page.stopLoading calls
  3 tasks outliving the fetch and firing against a closed page

Page.stopLoading takes no frame or loader argument - it is the Stop button, and it stops the whole
page. Verified directly: one call stopped a pending main frame and a pending iframe in the same
instant. So the other 10 calls were redundant, and because they landed at arbitrary later times
they could stop a *subsequent* navigation we actually wanted - which is the likeliest reason the
same URL fetched in 8s on one run and 35s on the next.

Replaced with a single deadline, awaited inline so nothing can outlive the fetch (there is no
create_task left in this file at all):

    navigate (bounded)  ->  wait the configured delay  ->  Page.stopLoading  ->  extract

The delay is measured from when navigation finished, not from when it started. Anchoring it to the
start would quietly rob a slow-loading page of its settle time, and letting JS-rendered content
appear after load is the whole point of the setting. Verified with a server that takes 5s to answer
and renders via JS 2s after load: total 9.6s for a 4s delay, and the late content is captured.

Because a page is never reliably "finished" - many sites navigate as part of their normal design -
the delay restarts when the MAIN frame replaces its document, so a redirect or interstitial gets
the same settle time the first document got. Iframes do not restart it, and it is capped by
BROWSER_CONTENT_READY_MAX_RESETS (default 2).

Only the existing "wait n seconds before extracting text" stays user-facing;
BROWSER_NAVIGATION_TIMEOUT_SECONDS is a safety net with a sane default rather than a second knob
for users to reason about. This matches what other scrapers do: bound the navigation, do not fail
when it times out, settle, then extract.

Timings are also more predictable now - the four reported URLs went from 5-35s of variance to
4.6-7.2s at a 3s delay, all with full content and a 200.

Tested: 11 passed pyppeteer browser suite, 7 passed playwright, 494 unit + llm.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>

---------

Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Detect Website Changes Automatically — Monitor Web Page Changes in Real Time
Monitor websites for updates — get notified via Discord, Email, Slack, Telegram, Webhook and many more.
Detect web page content changes and get instant alerts.
Ideal for monitoring price changes, content edits, conditional changes and more.
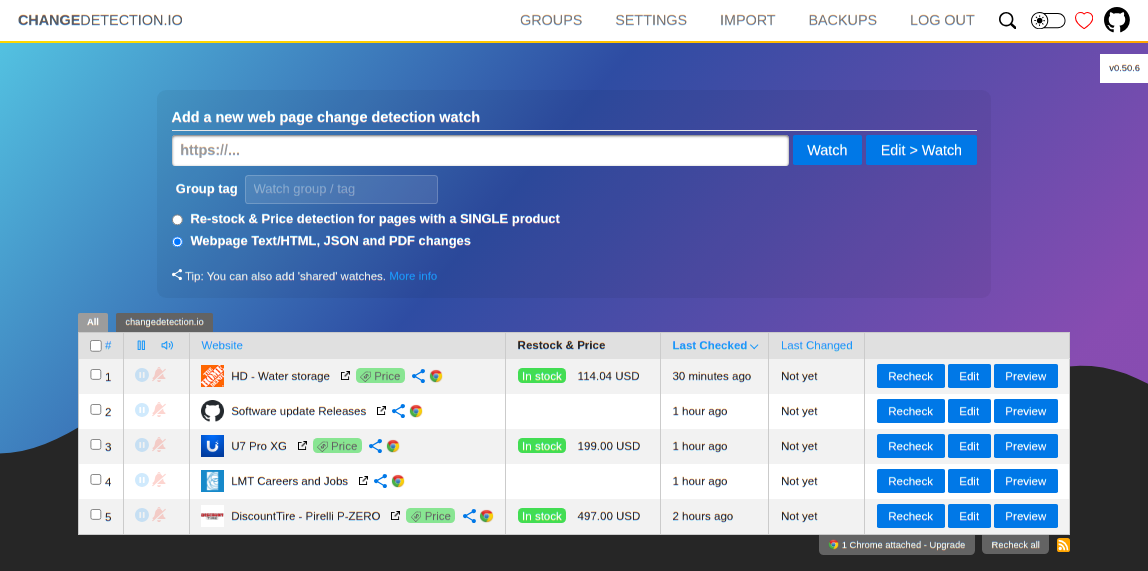


Get started with website page change monitoring straight away. Don't have time? Try our $8.99/month subscription, use our proxies and support! , half the price of other website change monitoring services!
- Chrome browser included.
- Nothing to install, access via browser login after signup.
- Super fast, no registration needed setup.
- Get started watching and receiving website change notifications straight away.
- See our tutorials and how-to page for more inspiration
AI-powered website change detection — smart alerts and plain-language summaries
Stop drowning in noise. Connect any LLM (OpenAI, Gemini, Anthropic, Ollama and more) and go from "something changed" to "only the thing you care about changed".
AI change detection rules — write a plain-English intent once: "notify me only when the price drops below $50", "alert me when the item comes back in stock", "ignore navigation and footer changes". The AI evaluates every detected diff against your intent and silently suppresses everything irrelevant. Fewer false positives, zero noise.
AI change summaries — instead of staring at a raw diff, your notification reads "Price dropped from $89.99 to $67.00" or "3 new products added to the listing". Works globally or per-watch, with full control over the prompt.
Works with any model you already pay for — GPT-4o-mini and Gemini Flash handle this well at fractions of a cent per check. Or run it entirely locally with Ollama, vLLM, LM Studio, or any OpenAI-compatible self-hosted endpoint — pick the OpenAI-compatible (vLLM, LM Studio, llama.cpp) option in the provider dropdown and point it at your server's /v1 URL. Powered by LiteLLM, giving you seamless access to 100+ supported providers and models.

Note: Available in our subscription/hosted service from June 2026
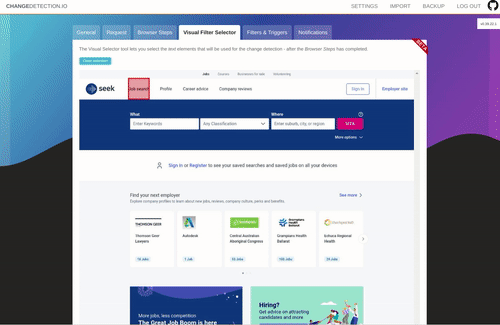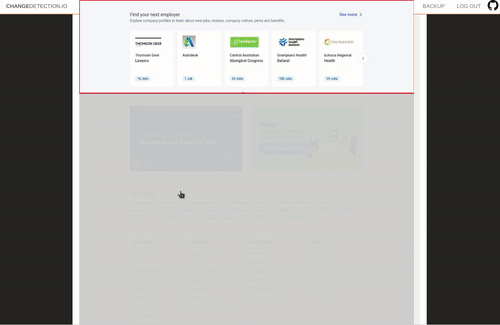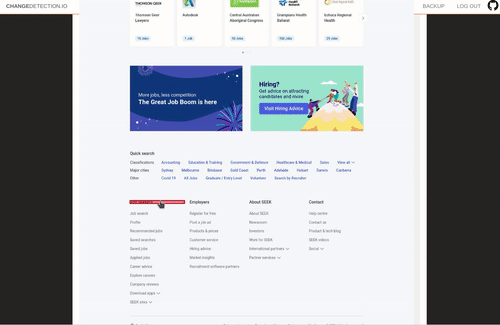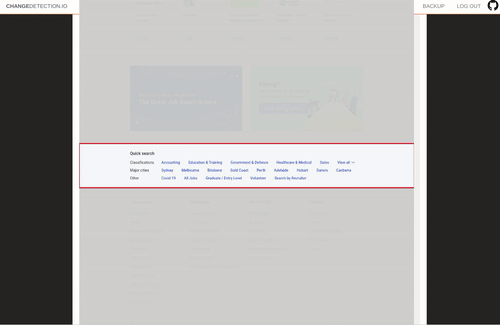
Target specific parts of the webpage using the Visual Selector tool.
Available when connected to a playwright content fetcher (included as part of our subscription service)
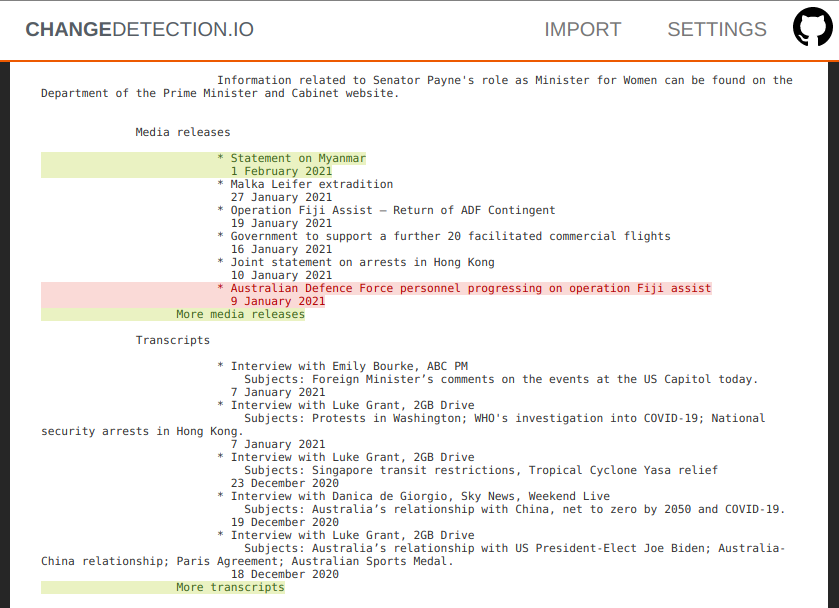
Easily see what changed, examine by word, line, or individual character.
Perform interactive browser steps
Fill in text boxes, click buttons and more, setup your changedetection scenario.
Using the Browser Steps configuration, add basic steps before performing change detection, such as logging into websites, adding a product to a cart, accept cookie logins, entering dates and refining searches.

After Browser Steps have been run, then visit the Visual Selector tab to refine the content you're interested in. Requires Playwright to be enabled.
Awesome restock and price change notifications
Enable the "Re-stock & Price detection for single product pages" option to activate the best way to monitor product pricing, this will extract any meta-data in the HTML page and give you many options to follow the pricing of the product.
Easily organise and monitor prices for products from the dashboard, get alerts and notifications when the price of a product changes or comes back in stock again!

Set price change notification parameters, upper and lower price, price change percentage and more. Always know when a product for sale drops in price.

Example use cases
- Products and services have a change in pricing
- Out of stock notification and Back In stock notification
- Monitor and track PDF file changes, know when a PDF file has text changes.
- Governmental department updates (changes are often only on their websites)
- New software releases, security advisories when you're not on their mailing list.
- Festivals with changes
- Discogs restock alerts and monitoring
- Realestate listing changes
- Know when your favourite whiskey is on sale, or other special deals are announced before anyone else
- COVID related news from government websites
- University/organisation news from their website
- Detect and monitor changes in JSON API responses
- JSON API monitoring and alerting
- Changes in legal and other documents
- Trigger API calls via notifications when text appears on a website
- Glue together APIs using the JSON filter and JSON notifications
- Create RSS feeds based on changes in web content
- Monitor HTML source code for unexpected changes, strengthen your PCI compliance
- You have a very sensitive list of URLs to watch and you do not want to use the paid alternatives. (Remember, you are the product)
- Get notified when certain keywords appear in Twitter search results
- Proactively search for jobs, get notified when companies update their careers page, search job portals for keywords.
- Get alerts when new job positions are open on Bamboo HR and other job platforms
- Website defacement monitoring
- Pokémon Card Restock Tracker / Pokémon TCG Tracker
- RegTech - stay ahead of regulatory changes, regulatory compliance
Need an actual Chrome runner with Javascript support? We support fetching via WebDriver and Playwright!
Key Features
- Lots of trigger filters, such as "Trigger on text", "Remove text by selector", "Ignore text", "Extract text", also using regular-expressions!
- Target elements with xPath 1 and xPath 2, CSS Selectors, Easily monitor complex JSON with JSONPath or jq
- Switch between fast non-JS and Chrome JS based "fetchers"
- Track changes in PDF files (Monitor text changed in the PDF, Also monitor PDF filesize and checksums)
- Easily specify how often a site should be checked
- Execute JS before extracting text (Good for logging in, see examples in the UI!)
- Override Request Headers, Specify
POSTorGETand other methods - Use the "Visual Selector" to help target specific elements
- Configurable proxy per watch
- Send a screenshot with the notification when a change is detected in the web page
We recommend and use Bright Data global proxy services, Bright Data will match any first deposit up to $150 using our signup link.
Please ⭐ star ⭐ this project and help it grow! https://github.com/dgtlmoon/changedetection.io/
Conditional web page changes
Easily configure conditional actions, for example, only trigger when a price is above or below a preset amount, or when a web page includes (or does not include) a keyword

Schedule web page watches in any timezone, limit by day of week and time.
Easily set a re-check schedule, for example you could limit the web page change detection to only operate during business hours. Or perhaps based on a foreign timezone (for example, you want to check for the latest news-headlines in a foreign country at 0900 AM),

Includes quick short-cut buttons to setup a schedule for business hours only, or weekends.
We have a Chrome extension!
Easily add the current web page to your changedetection.io tool, simply install the extension and click "Sync" to connect it to your existing changedetection.io install.

Goto the Chrome Webstore to download the extension. ( Or check out the GitHub repo )
Installation
Docker
With Docker composer, just clone this repository and..
$ docker compose up -d
Docker standalone
$ docker run -d --restart always -p "127.0.0.1:5000:5000" -v datastore-volume:/datastore --name changedetection.io dgtlmoon/changedetection.io
:latest tag is our latest stable release, :dev tag is our bleeding edge master branch.
Alternative docker repository over at ghcr - ghcr.io/dgtlmoon/changedetection.io
Windows
See the install instructions at the wiki https://github.com/dgtlmoon/changedetection.io/wiki/Microsoft-Windows
Python Pip
Check out our pypi page https://pypi.org/project/changedetection.io/
$ pip3 install changedetection.io
$ changedetection.io -d /path/to/empty/data/dir -p 5000
Then visit http://127.0.0.1:5000 , You should now be able to access the UI.
Now with per-site configurable support for using a fast built in HTTP fetcher or use a Chrome based fetcher for monitoring of JavaScript websites!
Updating changedetection.io
Docker
docker pull dgtlmoon/changedetection.io
docker kill $(docker ps -a -f name=changedetection.io -q)
docker rm $(docker ps -a -f name=changedetection.io -q)
docker run -d --restart always -p "127.0.0.1:5000:5000" -v datastore-volume:/datastore --name changedetection.io dgtlmoon/changedetection.io
docker compose
docker compose pull && docker compose up -d
See the wiki for more information https://github.com/dgtlmoon/changedetection.io/wiki
Different browser viewport sizes (mobile, desktop etc)
If you are using the recommended sockpuppetbrowser (which is in the docker-compose.yml as a setting to be uncommented) you can easily set different viewport sizes for your web page change detection, see more information here about setting up different viewport sizes.
Filters
XPath(1.0), JSONPath, jq, and CSS support comes baked in! You can be as specific as you need, use XPath exported from various XPath element query creation tools.
(We support LXML re:test, re:match and re:replace.)
Notifications
ChangeDetection.io supports a massive amount of notifications (including email, office365, custom APIs, etc) when a web-page has a change detected thanks to the apprise library. Simply set one or more notification URL's in the [edit] tab of that watch.
Just some examples
discord://webhook_id/webhook_token
flock://app_token/g:channel_id
gitter://token/room
gchat://workspace/key/token
msteams://TokenA/TokenB/TokenC/
o365://TenantID:AccountEmail/ClientID/ClientSecret/TargetEmail
rocket://user:password@hostname/#Channel
mailto://user:pass@example.com?to=receivingAddress@example.com
json://someserver.com/custom-api
syslog://
And everything else in this list!
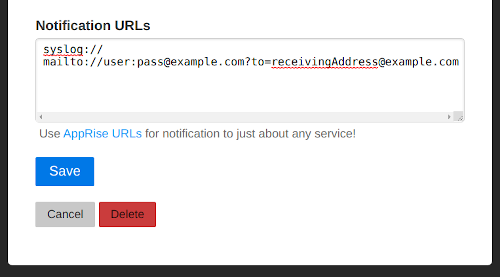
Now you can also customise your notification content and use Jinja2 templating for their title and body!
JSON API Monitoring
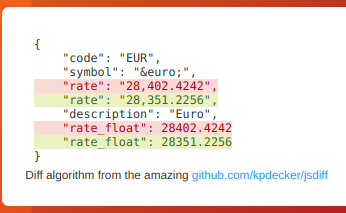
Detect changes and monitor data in JSON API's by using either JSONPath or jq to filter, parse, and restructure JSON as needed.
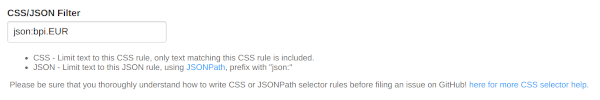
This will re-parse the JSON and apply formatting to the text, making it super easy to monitor and detect changes in JSON API results
JSONPath or jq?
For more complex parsing, filtering, and modifying of JSON data, jq is recommended due to the built-in operators and functions. Refer to the documentation for more specific information on jq.
One big advantage of jq is that you can use logic in your JSON filter, such as filters to only show items that have a value greater than/less than etc.
See the wiki https://github.com/dgtlmoon/changedetection.io/wiki/JSON-Selector-Filter-help for more information and examples
Parse JSON embedded in HTML!
When you enable a json: or jq: filter, you can even automatically extract and parse embedded JSON inside a HTML page! Amazingly handy for sites that build content based on JSON, such as many e-commerce websites.
<html>
...
<script type="application/ld+json">

{
   "@context":"http://schema.org/",
   "@type":"Product",
   "offers":{
      "@type":"Offer",
      "availability":"http://schema.org/InStock",
      "price":"3949.99",
      "priceCurrency":"USD",
      "url":"https://www.newegg.com/p/3D5-000D-001T1"
   },
   "description":"Cobratype King Cobra Hero Desktop Gaming PC",
   "name":"Cobratype King Cobra Hero Desktop Gaming PC",
   "sku":"3D5-000D-001T1",
   "itemCondition":"NewCondition"
}
</script>
json:$..price or jq:..price would give 3949.99, or you can extract the whole structure (use a JSONpath test website to validate with)
The application also supports notifying you that it can follow this information automatically
Proxy Configuration
See the wiki https://github.com/dgtlmoon/changedetection.io/wiki/Proxy-configuration , we also support using Bright Data proxy services where possible and Oxylabs proxy services.
Raspberry Pi support?
Raspberry Pi and linux/arm/v6 linux/arm/v7 arm64 devices are supported! See the wiki for details
Import support
Easily import your list of websites to watch for changes in Excel .xslx file format, or paste in lists of website URLs as plaintext.
Excel import is recommended - that way you can better organise tags/groups of websites and other features.
API Support
Full REST API for programmatic management of watches, tags, notifications and more.
- Interactive API Documentation - Complete API reference with live testing
- OpenAPI Specification - Generate SDKs for any programming language
Support us
Do you use changedetection.io to make money? does it save you time or money? Does it make your life easier? less stressful? Remember, we write this software when we should be doing actual paid work, we have to buy food and pay rent just like you.
Consider taking out an officially supported website change detection subscription , even if you don't use it, you still get the warm fuzzy feeling of helping out the project. (And who knows, you might just use it!)
Commercial Support
I offer commercial support, this software is depended on by network security, aerospace , data-science and data-journalist professionals just to name a few, please reach out at dgtlmoon@gmail.com for any enquiries, I am more than glad to work with your organisation to further the possibilities of what can be done with changedetection.io
Disclaimer
This software is provided "as-is", without warranty of any kind, express or implied, including but not limited to the warranties of merchantability, fitness for a particular purpose, and non-infringement. In no event shall the authors or copyright holders be liable for any claim, damages, or other liability, whether in an action of contract, tort, or otherwise, arising from, out of, or in connection with the software or the use or other dealings in the software.
Website content monitoring
You are solely responsible for ensuring that your use of this software complies with the terms of service, robots.txt directives, access policies, and all applicable laws of any website or service you choose to monitor. The authors and contributors of this software accept no liability whatsoever for how you choose to use it or for any consequences arising from that use.
AI / LLM features
If you choose to enable AI / LLM features, content detected on monitored websites — including page diffs and extracted text — will be transmitted to a third-party AI provider of your choosing, outside of this installation. You are solely responsible for:
- Ensuring such transmission is permitted by the terms of service of every website you monitor.
- Compliance with all applicable data-protection and privacy laws (including but not limited to GDPR) with respect to any personal data that may appear in monitored content.
- All API costs and charges levied by your chosen AI provider. This software has no visibility into or control over those charges.
- Any consequences arising from acting on AI-generated output.
AI and LLM models are known to hallucinate — producing plausible-sounding but factually incorrect, incomplete, or entirely fabricated output with apparent confidence. By design, LLMs may also omit or silently truncate relevant information during summarisation. AI output must never be relied upon as complete or accurate.
By using this software, and in particular any AI / LLM features, you personally indemnify and hold harmless the author(s), contributor(s), and any associated parties from and against any and all claims, damages, losses, costs, and expenses (including reasonable legal fees) arising out of or in connection with your use of this software.
Third-party licenses
changedetectionio.html_tools.elementpath_tostring: Copyright (c), 2018-2021, SISSA (Scuola Internazionale Superiore di Studi Avanzati), Licensed under MIT license
Contributors
Recognition of fantastic contributors to the project
Developer note: see translation guide for i18n template patterns and workflow.
- Constantin Hong https://github.com/Constantin1489